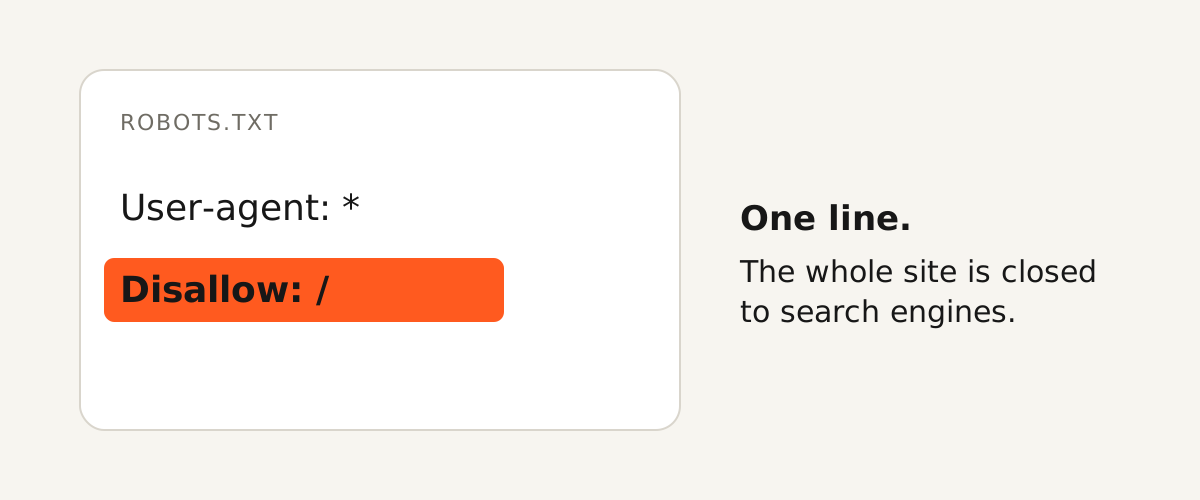
One wrong line in a robots.txt file can take a whole site out of Google. The most expensive of the common robots.txt issues is the oldest: a site launches with the staging rule Disallow: / still in place, and nobody notices until the enquiries stop. Here are eight issues and the fix for each.
The eight issues and their fixes
| Issue | Fix |
|---|---|
The staging rule Disallow: / survived the launch | Remove it on launch day, then open your own /robots.txt and read it |
| The file is not at the root of the host | It works only at /robots.txt, and each subdomain needs its own (Google, 2026) |
| Folders with CSS and JavaScript are blocked | Allow them: Google loads those files to see the page as a visitor does |
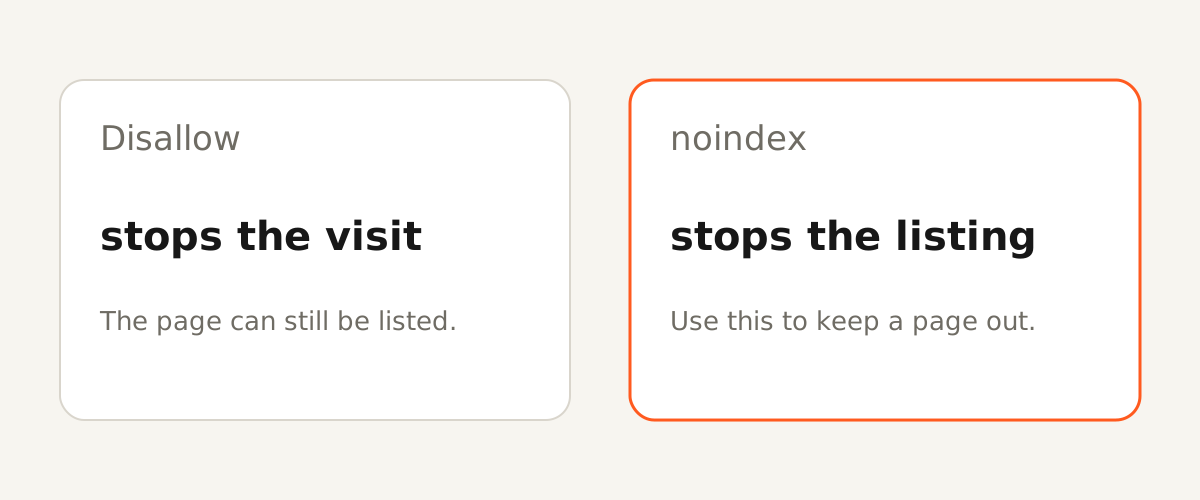
| A page is “hidden” with Disallow | Blocking is not removal. Use noindex or a password (Google Search Central, 2026) |
| Rules Google does not read, such as crawl-delay | Google supports four fields: user-agent, allow, disallow, sitemap (Google, 2026) |
| Wrong letter case in a path | Paths are case-sensitive: /Blog/ and /blog/ are two different rules |
| No sitemap line | Add Sitemap: with the full address of the sitemap |
| AI crawlers blocked without a decision | A site that opts out of OAI-SearchBot is not shown in ChatGPT search answers (OpenAI, 2026). Decide first, then write the rule |
How to check yours in ten minutes
Type your address followed by /robots.txt and read what is there. If you see Disallow: / under User-agent: *, call your developer now. Then open the robots.txt report in Google Search Console: it shows the file Google last fetched.